The model plans; the pipeline writes the SQL
Why doesn't the AI write the query?
How it works →A portfolio project · Google Cloud
Trellis is an analytics assistant over BigQuery. One Gemini model reads the question; everything else, from the SQL to the checks to the spend, is deterministic and inspectable.
One approved metric · a 17-row synthetic sample · a pilot behind sign-in, not a production system
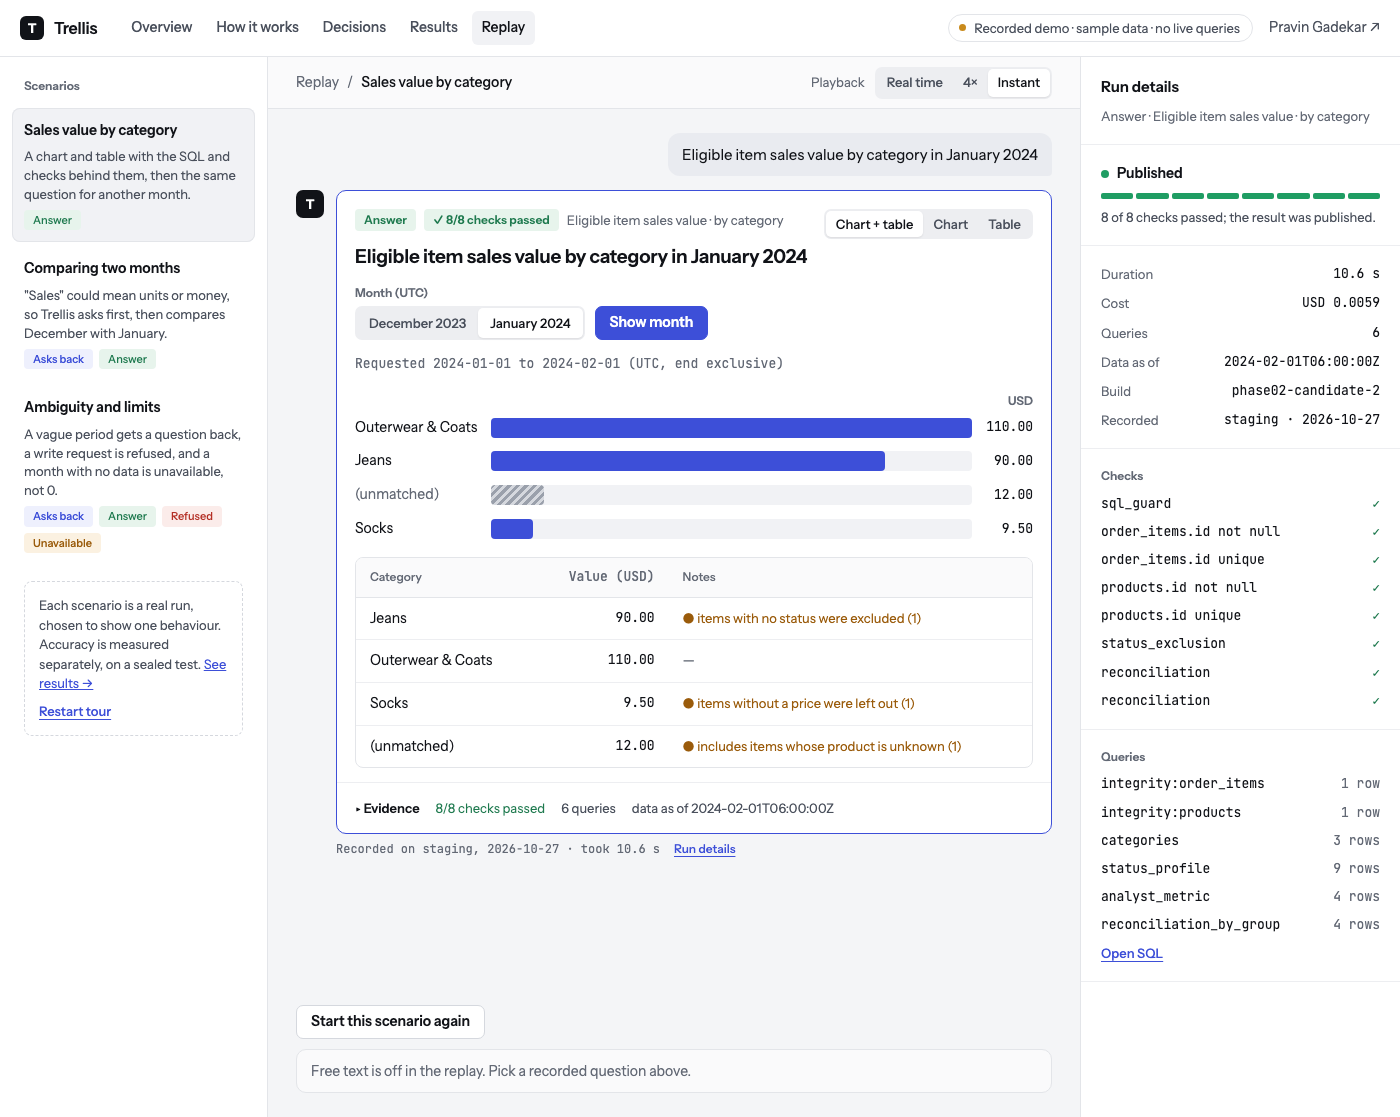
One real run · recorded 2026-10-27 · staging
Everything below is taken from the recorded run, not retyped. The same run plays in the replay.
The model reads the question and returns a typed intent, not SQL.
QuestionEligible item sales value by category in January 2024Answer kind and period, as published
Eligible item sales value · by category
Requested 2024-01-01 to 2024-02-01 (UTC, end exclusive)
The pipeline writes the one query for that intent. The month is a bound parameter, never pasted into the SQL.
Metric querySELECT COALESCE(p.category, '(unmatched)') AS grp, COUNTIF(oi.status IN ('Complete', 'Shipped')) AS eligible_items, COUNTIF(oi.status IN ('Complete', 'Shipped') AND NOT oi.sale_price IS NULL) AS priced_items, SUM(IF(oi.status IN ('Complete', 'Shipped'), oi.sale_price, NULL)) AS value_sum FROM order_items AS oi LEFT JOIN products AS p ON p.id = oi.product_id WHERE oi.created_at >= @window_start AND oi.created_at < @window_end GROUP BY grpEvery query passes a SQL allowlist, then runs in BigQuery as a read-only account under a byte cap. This answer took 6 queries.
Integrity, status and reconciliation checks decide whether the numbers may be published. Here 8 of 8 passed.
The answer carries a note for every row the rules affected, the data's coverage, and the limits that apply.
| Category | Value (USD) | Note |
|---|---|---|
| Jeans | 90.00 | items with no status were excluded (1) |
| Outerwear & Coats | 110.00 | — |
| Socks | 9.50 | items without a price were left out (1) |
| (unmatched) | 12.00 | includes items whose product is unknown (1) |
bigquery · bigquery-fixture · context dev_v1.3 · data as of 2024-02-01T06:00:00Z · covers 2023-12-01 to 2024-02-01 (end exclusive)
Recorded on staging, 2026-10-27 · phase02-candidate-2 · took 10.6 s · USD 0.0059
Why you can trust it
Why doesn't the AI write the query?
How it works →How does a query that runs still get rejected?
How it works →How can a chat tool have a hard budget?
How it works →Measured results
Each sealed set was written before the tuning it judged and run once. The bar, set in advance: at least 35 of 36 correct, no unsafe answers, guard rails passing and every run within its caps.
| Candidate | Sealed set | Correct | Unsafe | Verdict |
|---|---|---|---|---|
| 1 · the model wrote the SQL | final_v1 | 34 / 36 | 0 | Fail |
| 2 · the pipeline writes the SQL | final_v2 | 36 / 36 | 0 | Pass |
The design
Each page answers one question: what was decided, what it costs, and what was shown.
What isn't proven
The claims on this site are tagged by how they were shown. These are the weakest.
About the build
Pravin set every contract, threshold and budget and approved each phase gate. AI coding agents wrote the code under those gates; models from other providers reviewed the material changes, and their findings were checked against the code before anything was accepted. The phase records keep every failed check alongside the passes.
Built on Cloud Run, Identity-Aware Proxy, BigQuery, Vertex AI (Gemini) and Firestore, defined in Terraform.